
Audio By Carbonatix
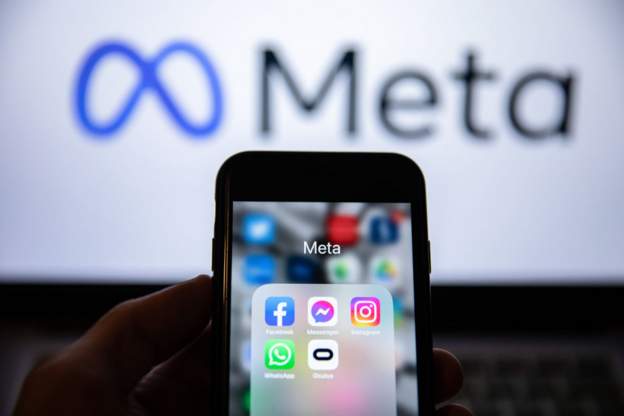
Facebook users are now able to delete some personal information that can be used by the company in the training of generative artificial intelligence models.
Meta updated the Facebook help center resource section on its website this week to include a form titled “Generative AI Data Subject Rights,” which allows users to “submit requests related to your third party information being used for generative AI model training.”
The company is adding the opt-out tool as generative AI technology is taking off across tech, with companies creating more advanced chatbots and turning simple text into sophisticated answers and images. Meta is giving people the option to access, alter or delete any personal data that was included in the various third-party data sources the company uses to train its large language and related AI models.
On the form, Meta refers to third-party information as data “that is publicly available on the internet or licensed sources.” This kind of information, the company says, can represent some of the “billions of pieces of data” used to train generative AI models that “use predictions and patterns to create new content.”
In a related blog post on how it uses data for generative AI, Meta says it collects public information on the web in addition to licensing data from other providers. Blog posts, for example, can include personal information, such as someone’s name and contact information, Meta said.
The form doesn’t account for a user’s activity on Meta-owned properties, whether it’s Facebook comments or Instagram photos, so it’s possible the company could potentially use such first-party data to train its generative AI models.
A Meta spokesperson said that the company’s newest Llama 2 open-source large language model “wasn’t trained on Meta user data, and we have not launched any Generative AI consumer features on our systems yet.”
“Depending on where people live, they may be able to exercise their data subject rights and object to certain data being used to train our AI models,” the spokesperson added, referring to various data privacy rules outside the U.S. that give consumers more control over how their personal data can be used by tech firms.
Like many tech peers, including Microsoft, OpenAI and Google parent Alphabet, Meta gathers enormous quantities of third-party data to train its models and related AI software.
“To train effective models to unlock these advancements, a significant amount of information is needed from publicly available and licensed sources,” Meta said in the blog post. The company added that “use of public information and licensed data is in our interests, and we are committed to being transparent about the legal bases that we use for processing this information.”
Recently, however, some data privacy advocates have questioned the practice of aggregating vast quantities of publicly available information to train AI models.
Last week, a consortium of data protection agencies from the U.K., Canada, Switzerland and other countries issued a joint statement to Meta, Alphabet, TikTok parent ByteDance, X (formerly known as Twitter), Microsoft and others about data scraping and protecting user privacy.
The letter was intended to remind social media and tech companies that they remain subject to various data protection and privacy laws around the world and “that they protect personal information accessible on their websites from data scraping, particularly so that they are compliant with data protection and privacy laws around the world.”
“Individuals can also take steps to protect their personal information from data scraping, and social media companies have a role to play in enabling users to engage with their services in a privacy protective manner,” the group said in the statement.
Here’s how you can delete some of your Facebook data used for training generative AI models:
- Go to the “Generative AI Data Subject Rights” form on Meta’s privacy policy page about generative AI.
- Click the link for “Learn more and submit requests here.”
- Choose from three options that Meta says “best describes your issue or objection.”
The first option lets people access, download, or correct any of their personal information gleaned from third-party sources that’s used to train generative AI models. By choosing the second option, they can delete any of the personal information from those third-party data sources used for training. The third option is for people who “have a different issue.”
After selecting one of the three options, users will need to pass a security check test. Some users have commented that they’re unable to finish completing the form because of what appears to be a software bug.
Latest Stories
-
Power restoration fault suspected in Kumasi Central Market fire
3 hours -
The 7-foot giant of Ngleshie Amanfro: Seven-foot Ghanaian Ephraim Saawa dreams of joining the national basketball team
4 hours -
Government promises support for Kumasi Central Market fire victims
4 hours -
Vibes The Movie: Big Ghun’s Ghanaian film earns five nominations at 2026 REFFA
4 hours -
MamaCare CEO warns unresolved conflicts among health workers could undermine maternal and neonatal care
5 hours -
Health professionals urged to translate medical knowledge into practice to save mothers
5 hours -
Conflicts among care providers linked to maternal, neonatal deaths – Expert
6 hours -
GIS marks 10th TIME conference, champions improved teaching practices
6 hours -
BRICS Or Balance? What Ghana’s bid really means
7 hours -
GPRTU wants full TRAFFITECH-GH implementation to start in 2027
7 hours -
Mahama announces plans to import electric wheelchairs for PWDs
7 hours -
KGL U17 Colts 2026: Western beat Prempeh Elite Academy to set up final final with Greater Accra Region
7 hours -
Late Solanke strike salvages 10-man Spurs draw at Man United
8 hours -
Gender Ministry to monitor welfare of Nana Akua Addo’s children amid domestic violence case
8 hours -
Benedict Okyere Yeboah: Ghana’s football problem goes beyond sacking a coach
8 hours